ForeTac-VLA: A Forecasting-Based Tactile-Vision-Language-Action Model for Contact-Rich Robotic Manipulation
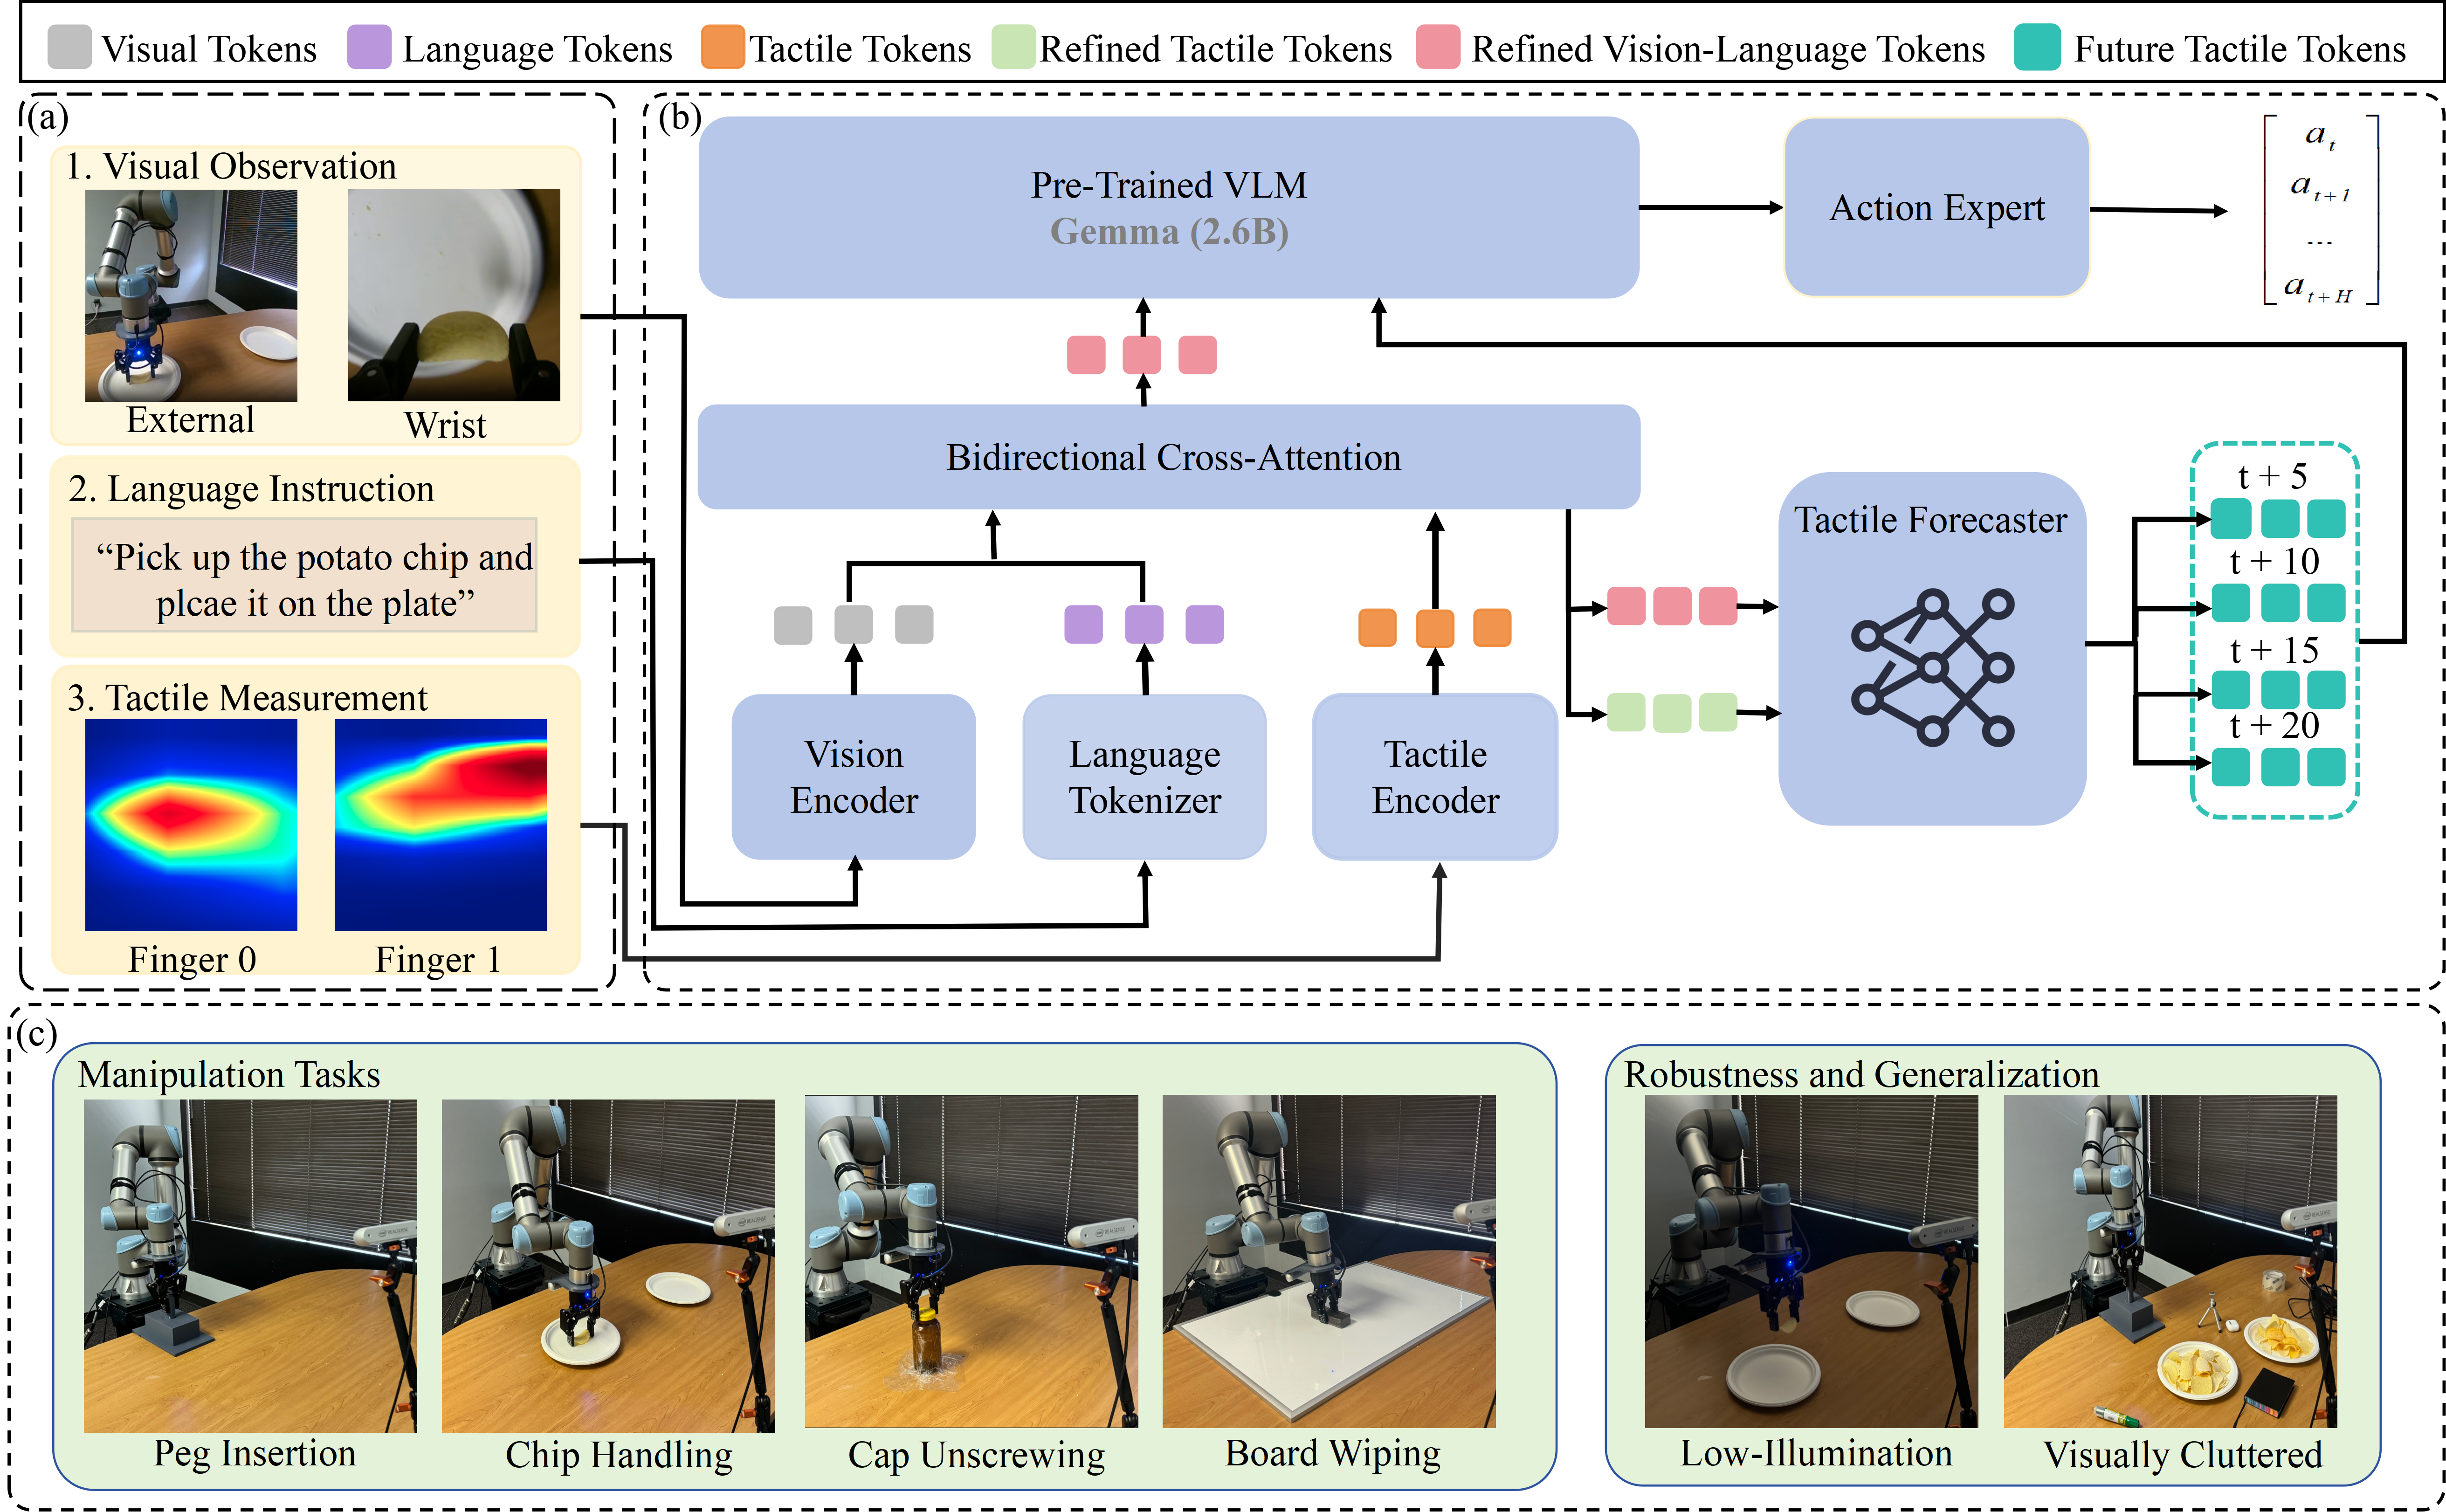
Forecasting future touch for contact-aware robotic manipulation.
Four real-world contact-rich manipulation tasks
Forecasting future touch for contact-aware robotic manipulation.
Four real-world contact-rich manipulation tasks
ForeTac-VLA integrates recent tactile measurements with vision-language features through bidirectional cross-attention and predicts multi-step future tactile states to directly condition action generation.
Each task compares ForeTac-VLA with three baselines under the same real-world contact-rich manipulation setting. All task demonstration videos are shown at 1.5× speed.
Precise contact alignment during insertion.
Stable grasping of fragile objects without excessive force.
Rotational manipulation with continuously evolving contact.
Sustained surface contact during long-horizon manipulation.
Each model is evaluated over 20 trials per task. ForeTac-VLA achieves a 95.0% average success rate, outperforming the Fine-tuned VLA by 36.25 percentage points and the strongest tactile-enhanced baseline by 22.50 percentage points.
| Model | Peg Insertion | Chip Handling | Cap Unscrewing | Board Wiping | Average |
|---|---|---|---|---|---|
| ACT | 2/20 | 5/20 | 0/20 | 4/20 | 13.75% |
| Fine-tuned VLA | 13/20 | 11/20 | 12/20 | 11/20 | 58.75% |
| FiLM-Fusion TacVLA | 14/20 | 14/20 | 16/20 | 13/20 | 71.25% |
| Concat-and-Gating TacVLA | 16/20 | 13/20 | 15/20 | 14/20 | 72.50% |
| ForeTac-VLA (Ours) | 20/20 | 19/20 | 19/20 | 18/20 | 95.00% |
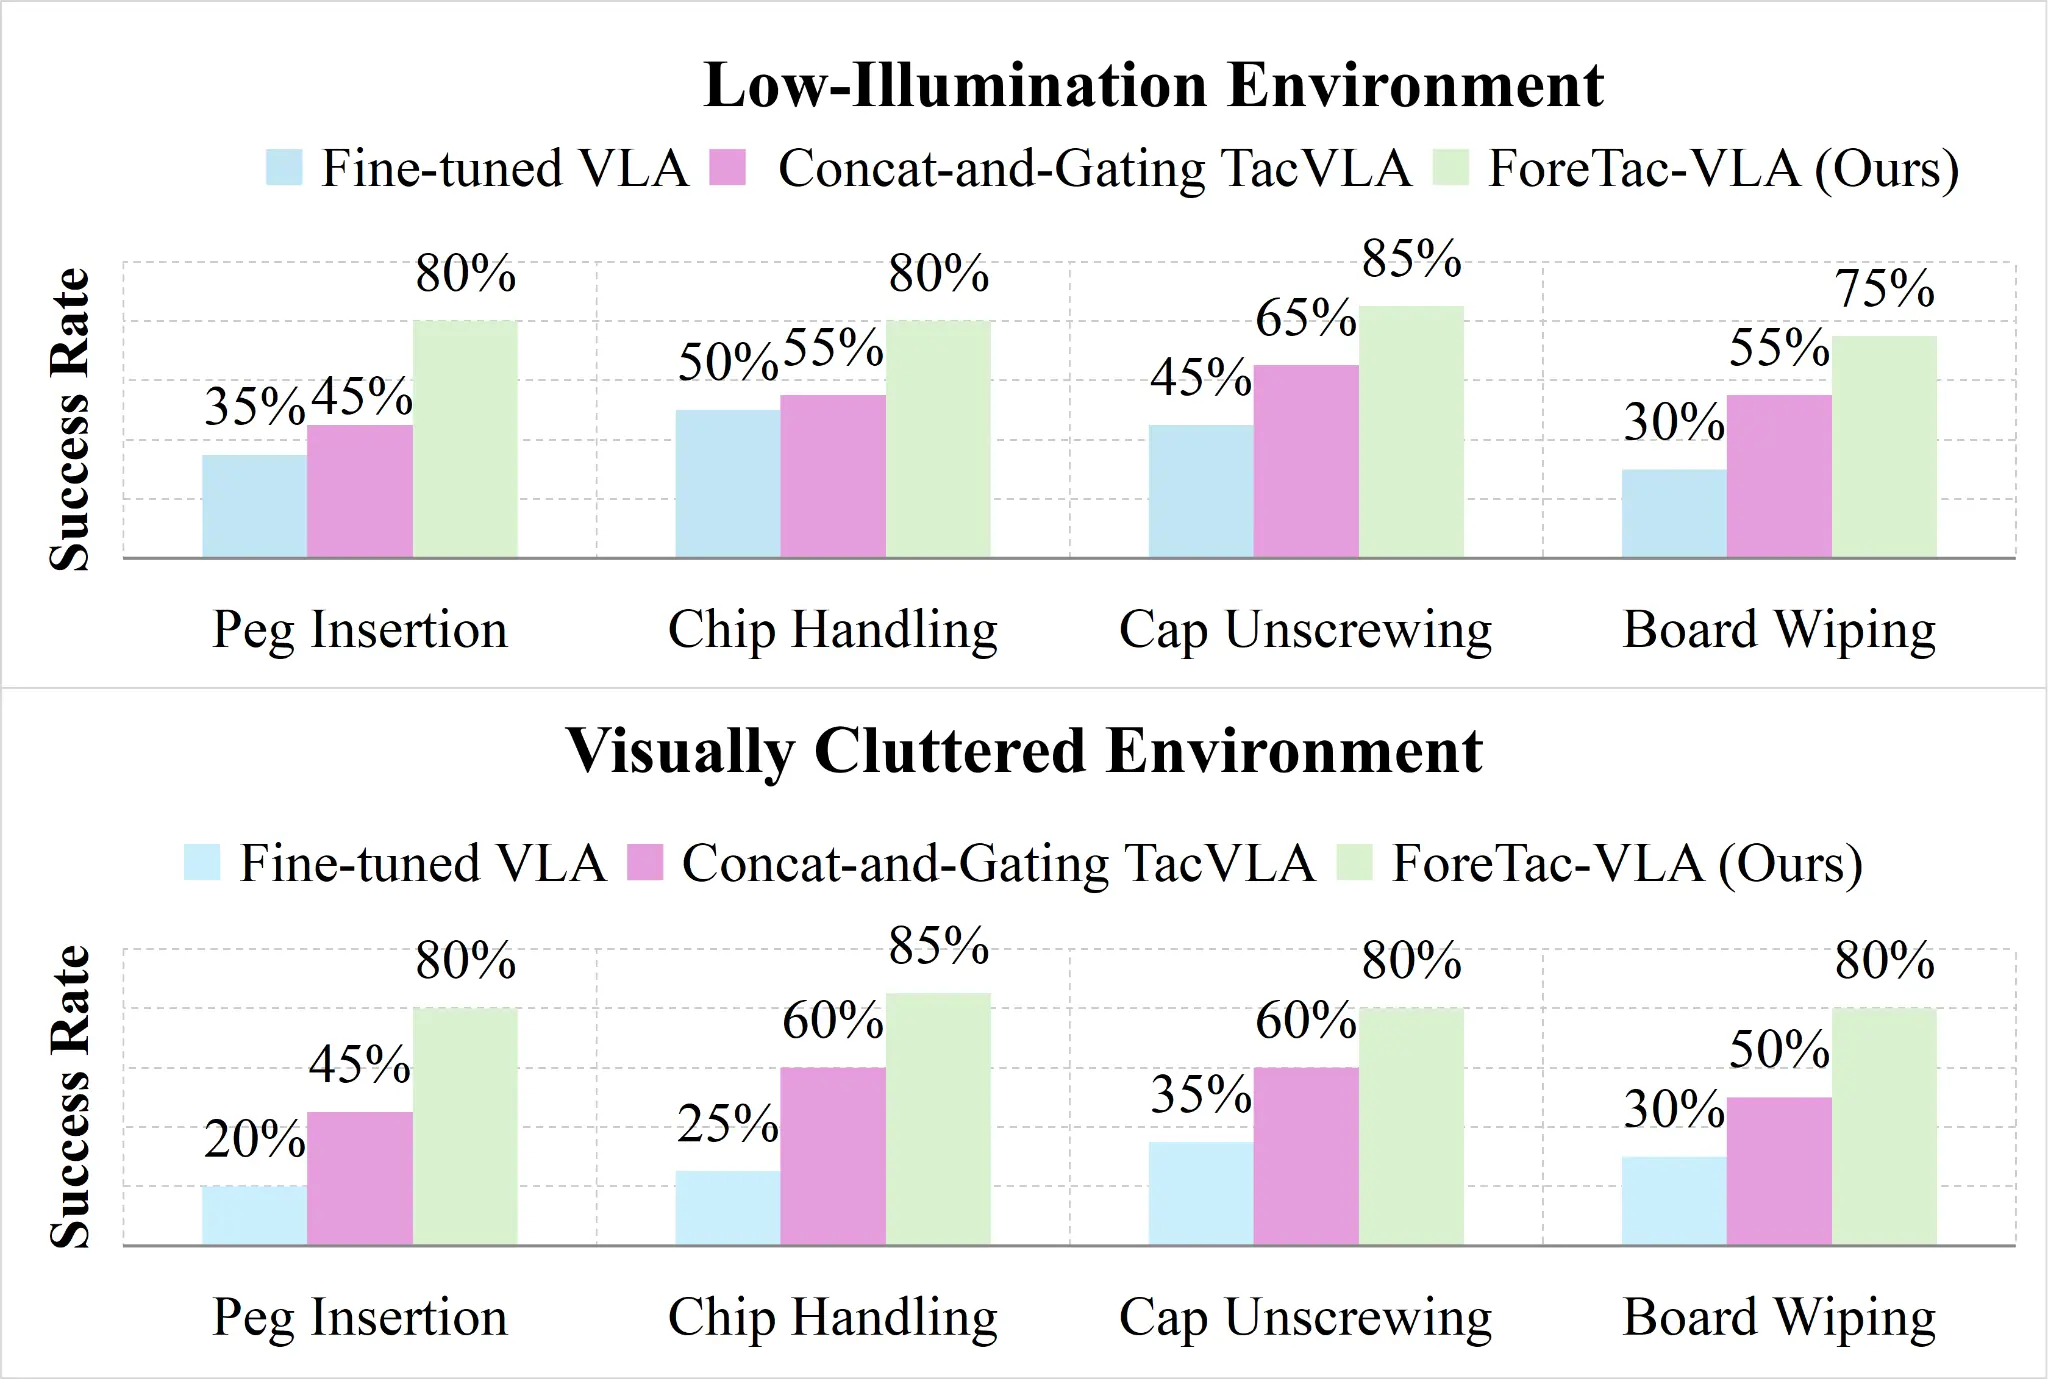
ForeTac-VLA is evaluated across all four tasks under challenging visual conditions. All generalization videos are shown at 5× speed.
Paper, code, and citation information will be released following publication.